


CodeCanyon Crawlomatic - WordPress Plugin
The WordPress post generator plugin creates unique posts efficiently. Its automation features streamline content creation across multiple sites. With customizable settings, it simplifies the process while maintaining flexibility. This plugin revolutionizes how posts are generated in WordPress.
Plugin Features
It automatically scrapes content from various sources, reducing manual effort significantly. By generating posts based on defined criteria, it ensures relevance and timeliness. The plugins functionality extends to managing metadata and categories, enhancing SEO optimization seamlessly. It empowers users to curate engaging content effortlessly.
The plugins multi-site support enables content creation for diverse WordPress installations simultaneously. This capability is invaluable for managing large-scale content strategies efficiently. Its intuitive interface and robust features make it a go-to tool for content managers seeking productivity enhancements. Its impact on streamlining workflows is remarkable.
By scheduling post generation at preferred intervals, users can maintain a consistent publishing cadence. The plugins systematic approach to content creation ensures a steady flow of fresh posts. This reliability is crucial for maintaining audience engagement and SEO performance. It empowers content creators with the tools to stay consistent and relevant.
With built-in monitoring and reporting functionalities, CodeCanyon Crawlomatic provides insights into post performance. It tracks key metrics to measure the effectiveness of generated content. These analytics help users refine their content strategies for optimal results. The plugins data-driven approach enhances content creation strategies significantly.
The plugins seamless integration with WordPress ensures a smooth user experience without compatibility issues. Its updates and enhancements reflect a commitment to staying current with WordPress developments. As a pivotal tool in content management, it upholds WordPress standards while pushing the boundaries of content automation. Its impact on streamlining content workflows is transformative.
Specifications:
| Release date: | 12-07-2019 | |
| Last updated: | 20-05-2026 | |
| Type: | Paid | |
| License: | GPL | |
| Subject: | Miscellaneous | |
| Compatibility: | W5.x W6.x | |
| Includes: | Plugin | |
| Language packs: |

|
|
| Developer: | CodeCanyon | |
| Rating: | ||
Share with your friends!
Guide to Configuring and Safely Using CodeCanyon Crawlomatic
CodeCanyon Crawlomatic is a WordPress plugin for controlled crawling and scraping that turns URLs discovered on an external site into posts, pages, products, or any other content type you choose. This guide does not simply restate the product page. Instead, it explains how to approach the plugin as a working tool: what to check before installation, which rules to create first, how to choose selectors, how to avoid a flood of low-quality imports, and how to tell whether a rule actually works.
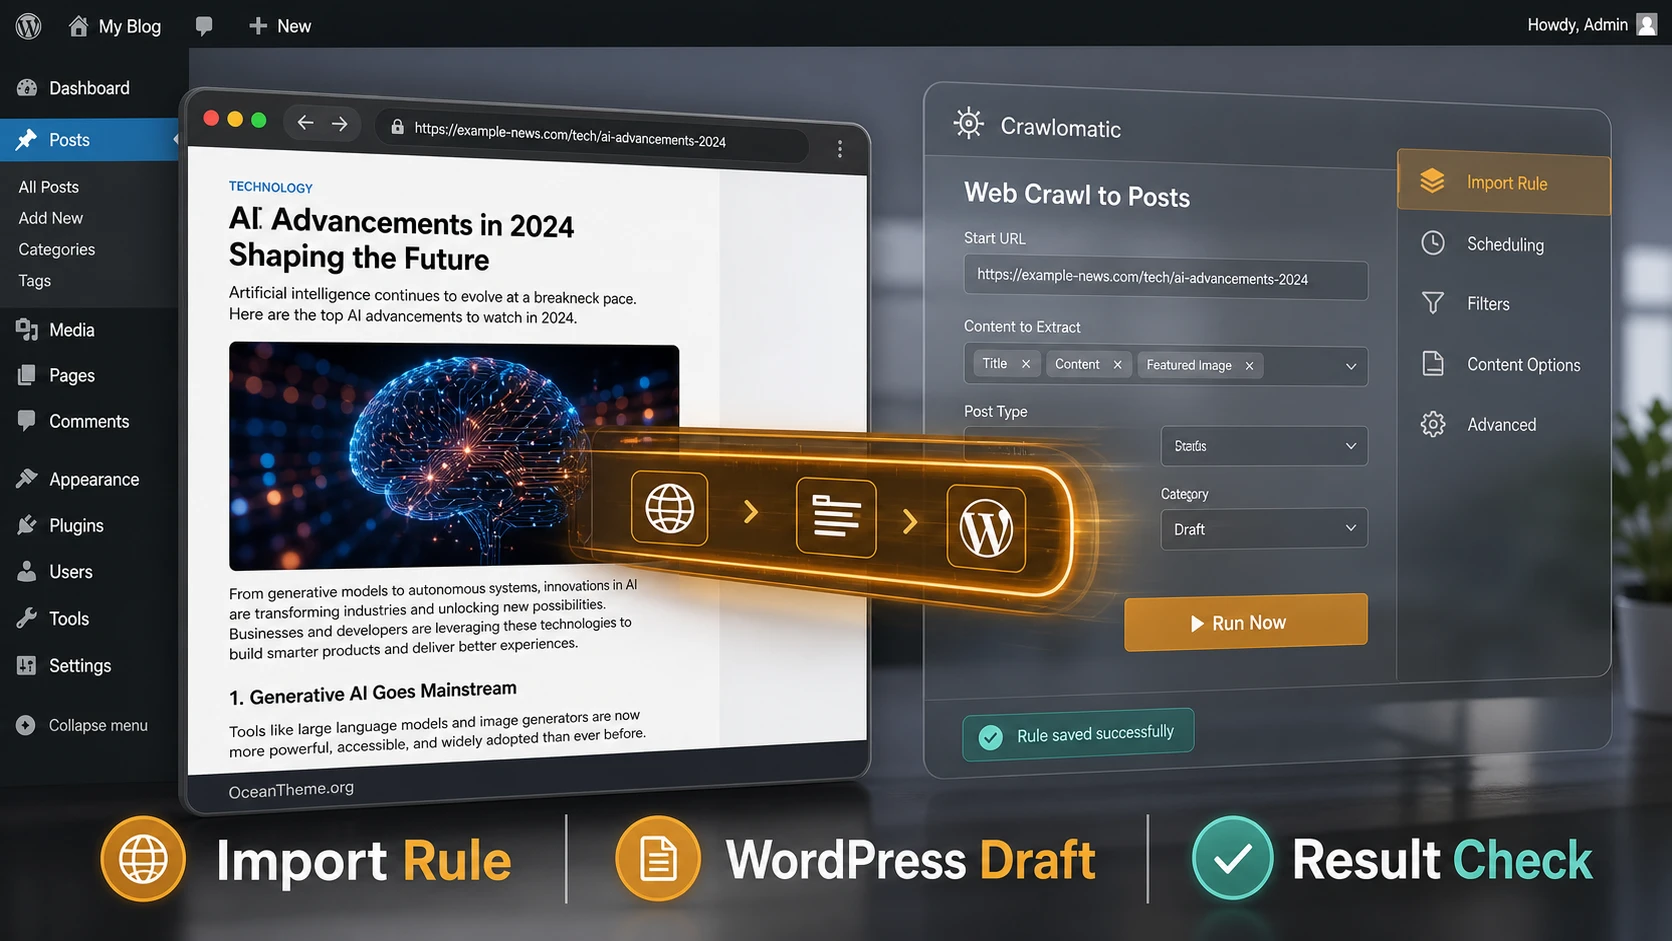
The key idea is simple: Crawlomatic is only useful when you have a clear source, a permitted content usage model, a limited set of pages, and defined quality criteria. If you turn it on as an "automatic post factory" with no constraints, it will quickly create duplicates, overly short posts, broken images, unnecessary links, and rights-related problems. That is why setup should revolve not around the number of published items, but around the chain source - rule - template - verification - rollback.
This article includes a practical scenario: import a selected group of items from a source section into WordPress drafts, clean out unnecessary blocks, save the image, assign a category, verify the result, and only then enable a schedule. We will also cover the live scraper shortcode [crawlomatic-scraper], troubleshooting slow performance, cases where a rule does not create new posts, and comparable alternatives for jobs where Crawlomatic may not be the best fit.
One important limitation: the plugin can technically pull data from web pages, but that does not override the source site's rules, copyright, terms of use, robots.txt, or reasonable load on someone else's server. The training scenario below assumes you are working with your own source, a partner site, open data, a test copy, or content you have a clear right to use.
How Crawlomatic Turns a Source into WordPress Posts
In a normal WordPress publishing flow, a person opens the editor, pastes a title, text, image, and category, then clicks Publish. Crawlomatic performs that chain programmatically. You provide a starting URL, the plugin extracts links from that page, visits the discovered URLs, finds the necessary parts of the HTML, builds a post from them, and saves it with the selected status. That is why the product should be treated not as a magic button, but as an import rule builder.
A rule has several layers. The first layer is where to look for links. The second is which links to take and how deeply to crawl the site. The third is what to extract from each discovered page: the title, main content, image, date, categories, tags, and additional fields. The fourth is how to build the WordPress post: which status to assign, which category to use, which content template to apply, whether to copy images, whether to remove extra links, whether to add a canonical tag, and whether to limit text length.
This model is especially useful when the source is consistent. For example, a partner site may have a section with announcements, an older project may have an archive of pages, a catalog may have similarly structured product cards, or a news section may have a stable title and content block layout. If the structure changes from page to page, the rule needs to be built more carefully: test the selectors first, then import a small batch into drafts, and only expand the scope after verification.
What can actually be automated
Crawlomatic can create posts, pages, and custom post types, assign an author, status, categories, and tags, pull in a featured image, work with post templates, and use built-in variables like %%item_title%%, %%item_content%%, %%item_url%%, and %%item_img_url%%. The documentation also covers rules for full content query, word-based filtering, minimum and maximum length, removing elements by ID or class, logging settings, and cleaning up old logs.
A separate feature is [crawlomatic-scraper]. This is not a bulk post import tool, but a shortcode for displaying a discovered fragment directly inside a post, page, or widget. It supports CSS selector, XPath, regex, caching, timeout, output format selection, and error handling. That mode is useful for small updated fragments, but it is riskier for page speed if you disable caching or set the timeout too high.
What you should not automate without editorial review
If the source is not yours, you should not import full articles without permission. If the source loads data through heavy JavaScript, you may need headless modes or an external service, which adds latency, cost, and more points of failure. If the source site changes its HTML frequently, a selector may suddenly start pulling a menu, an ad block, or an empty container. That is why, for real publishing workflows, it is better to keep the status at Draft or Pending until you are sure the rule is stable.
Practical rule: start with one source, one category, and a small post limit. If the first batch comes through cleanly, then expand the crawl depth, schedule, and the number of items per run.
Who this plugin is for, and where it is unnecessary
CodeCanyon Crawlomatic is best suited for site owners who already understand the structure of the source and want to eliminate repetitive manual work. That might mean moving your own old HTML archive into WordPress, collecting partner announcements, importing listings from an open catalog with permission, preparing drafts for an editor, or maintaining an internal knowledge base where each new source page should become a draft.
The plugin is especially appropriate when you have uniform pages: the same title container, a stable content block, a predictable image, and clear categories. In that kind of setup, you can tune the selector once, then control the results through logs and a small publishing limit. If the source provides RSS, XML, JSON, or an API, compare those options first: sometimes a feed importer or API integration is simpler and more stable than scraping HTML.
Good use cases
- Migrating your own older site, where pages have similar HTML and need to be turned into WordPress drafts.
- A partner catalog where the source owner has permitted the import of descriptions, images, and links.
- A news portal where an editor reviews every post before publication.
- A test content database for a theme, template, search, filtering, or demo site.
- A live block with a small data fragment, provided the source is stable and the shortcode runs through cache.
Poor use cases
Crawlomatic should not replace an editorial strategy. If the task sounds like "fill the site with anything," the result is almost always weak. Search engines and users respond poorly to duplicates, machine-reassembled third-party content, and pages with no added value. The plugin also will not solve the problem of a source that blocks requests, requires authentication, constantly changes the DOM, delivers content only after complex user actions, or forbids data reuse.
Security matters even more on sites with sensitive user roles, many authors, and open registration. Crawlomatic has had fixes related to shortcode callback handling and older vulnerabilities. So before installation, you should check not only the features, but also the current secure release line, user roles, publishing permissions, and access to the plugin settings.
What to check before installation
Before installing Crawlomatic, do a brief technical and editorial audit. That takes less time than sorting through a hundred incorrectly imported posts. Start with a test copy of the site. Even if the product page says the plugin is compatible with current WordPress versions, your specific theme, builder, cache plugin, security plugin, and hosting limits can still affect imports, image saving, and cron execution.
Technical readiness of the site
Make sure you have a recent backup, administrator access, a way to disable the plugin through the admin area or your hosting file manager, a reasonable PHP execution limit, and enough space for media files. Crawlomatic can download images, create attachments, and store logs. If the site is already close to its disk quota, importing with images will create a new problem very quickly.
- Install the plugin on staging or a local copy first if the site is already serving traffic.
- Verify that the ZIP archive came from a trusted source and matches a current release with security fixes.
- Restrict access to the plugin settings to administrators or trusted editors.
- Review who has the
Author,Editor, andAdministratorroles, especially if the shortcode might be used in user-generated content. - Make sure cache, firewall, and object cache do not interfere with cron execution or media file saving.
Readiness of the source
Open the source site in a normal browser and look at exactly what you want to import. Find the starting page, the list of links, an example target page, the main text container, the title, the image, the date, and the category. If you cannot explain with your own eyes where the needed data lives on the page, the plugin will not reliably figure it out for you either.
Check robots.txt, terms of use, update frequency, and server load. Even when it is technically possible to make many requests, that does not mean you should. For stable operation, use a moderate schedule, a small Max Posts At A Time, caching for live fragments, and a clear user agent. If the site serves different HTML to users in different regions or requires cookies, test especially carefully.

Content criteria
Define what counts as a successful post. For example: the title is at least five words long, the main text is above a minimum length, there is a featured image, no navigation blocks are included, the source link is preserved, a category is assigned, and the post stays in Draft. Those criteria later become settings: word limits, required and banned words, query string, content template, and publication status.
Installation and the first check in the admin area
If you already have the plugin ZIP archive, installation follows the standard WordPress flow: Plugins, Add New, Upload Plugin, choose the archive, install it, and click Activate. You do not need to configure external API keys for basic HTML crawling, but certain modes such as HeadlessBrowserAPI, external translators, proxies, or a text spinner require their own settings and should only be enabled when there is a real need.
After activation, do not start with a mass schedule. Open the plugin menu and find the general settings. Crawlomatic documentation describes Main Settings, logging, rule timeout, log cleanup, email summary, publishing limits, and image parameters. On day one, you do not need every feature, only the ones that protect the site from chaos: logs, drafts, a small limit, verifiable selectors, and a restricted source.
Initial settings to use
- Enable rule logging, but do not leave detailed logging on for long, because it can increase log size quickly.
- Set a safe publication status:
DraftorPending. - Limit the number of posts per run with
Max Posts At A Time. - Keep the schedule infrequent until you verify the quality of the first batch.
- Enable local image copying only if you have the rights to those images and enough space in the media library.
- Check the settings for removing links, HTML elements, and internal blocks before bulk import.
For the first test, it is convenient to create a separate category such as "Import - Review" and a separate author. That way you can immediately see which materials were created by the plugin, keep them separate from editorial posts, and remove test entries without risking your regular content.
How to tell whether the installation went well
A successful installation does not mean the rule already works. First, make sure the plugin menu opens, settings are saved, PHP errors do not appear, logs are accessible, and running a test rule does not lead to a white screen or a frozen admin area. If security errors, strange server warnings, or file write failures appear after saving settings, stop and check filesystem permissions, the PHP version, and the DOM, mbstring, iconv, and json extensions.
Detailed Setup of the Web Crawl to Posts Rule
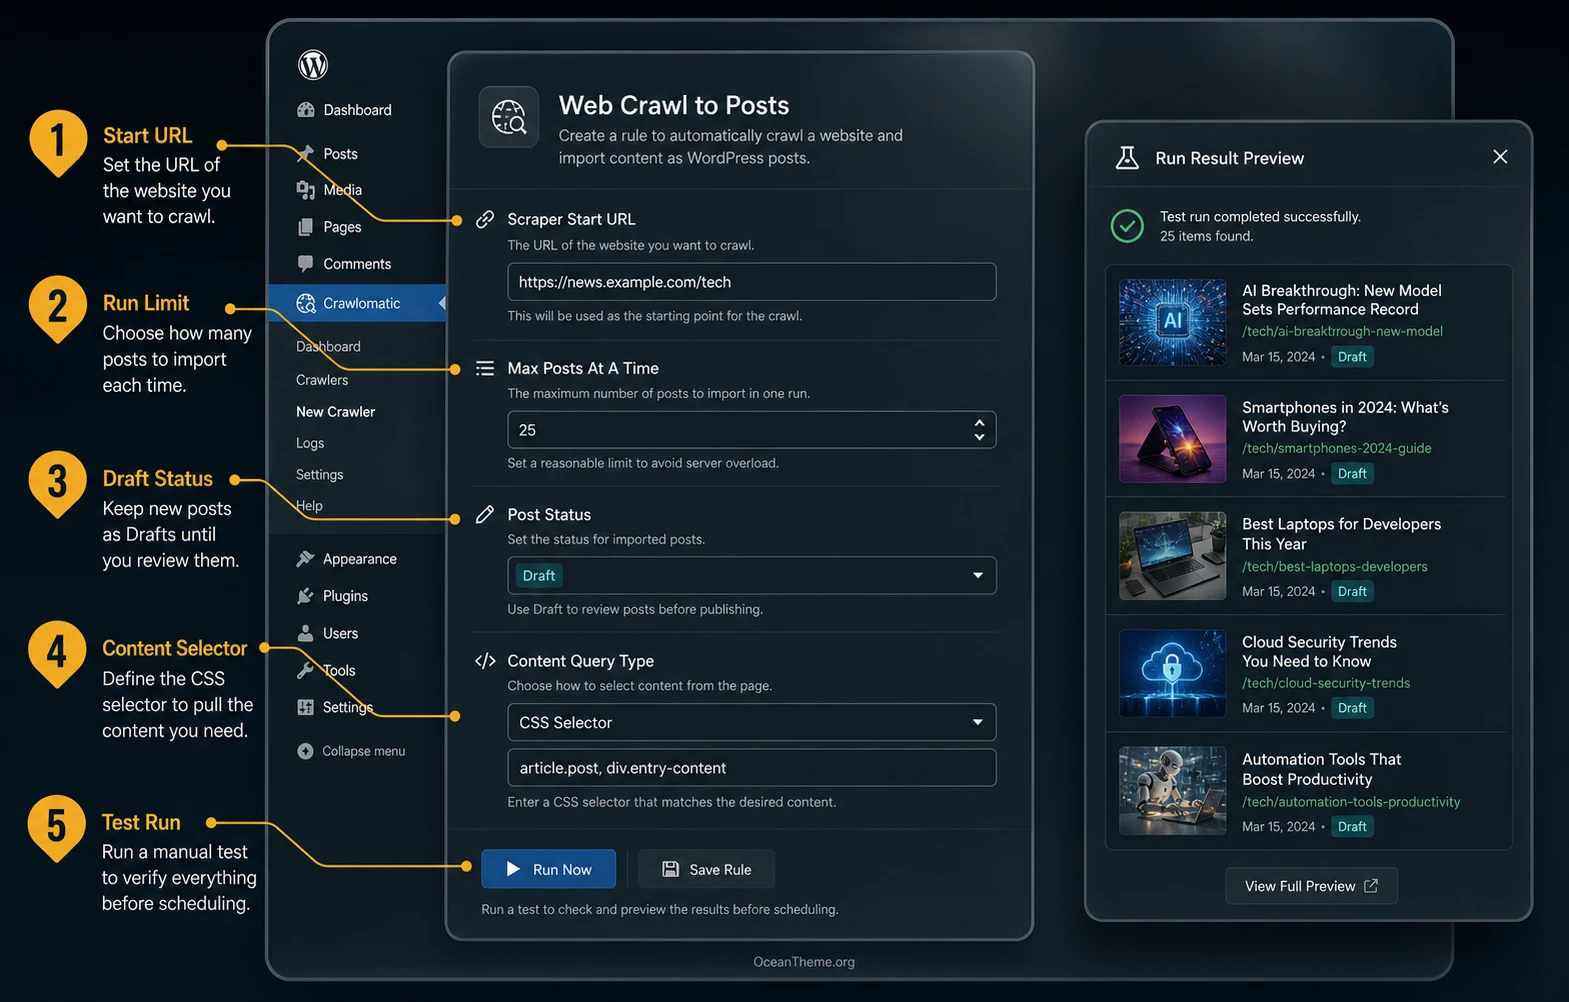
The main working screen in Crawlomatic is the import rule. In the documentation, it is built around Scraper Start URL, Schedule, Max Posts At A Time, Post Status, Item Type, Post Author, Active, information about created items, and the Run Now action. Your job is to build the rule so it creates a predictable draft, not one that tries to guess the entire site.
Starting URL and crawl depth
Scraper Start URL is your entry point. If you specify the home page of a large site, the plugin may discover too many irrelevant links. It is better to start with a specific section, category, sitemap file, or list page that contains only the material you want. If the settings include a restriction on external links, enable it for most scenarios. The documentation explicitly warns that allowing external links can lead to unpredictable publications.
Crawl depth determines how far the plugin will go from the starting page. For the first rule, a shallow depth is often enough. A deeper crawl is only necessary if the source is structured like category -> subcategory -> item and you understand that structure. The deeper the crawl, the higher the risk of capturing archives, tag pages, comment pagination, service URLs, and irrelevant sections.
Status, author, and post type
For a real working setup, choose the post type based on the task: standard content goes to post, static pages to page, catalogs or listings to a custom post type, and WooCommerce scenarios to product if that matches your structure and settings. It is best to leave the Published status for later. Until the rule has been tested across several batches, the safest status is draft.
The author matters too. If all imported items come from a dedicated technical author, they are easier to filter, review, remove, and exclude from internal editorial reports. Do not use a real editor as the author of automated publications unless that editor reviews every entry.
Limits and schedule
Max Posts At A Time limits how many posts are created per run. This is your safety net for cases where the rule finds hundreds of links. It is best to enable the schedule only after a manual Run Now and a review of the results. If the source updates rarely, do not schedule runs too frequently. If it changes quickly, first ask whether you really need every change published, or whether a periodic summary would be enough.
Selectors for content, title, and image
Crawlomatic documentation allows you to set a query type and query string for the main content, title, featured image, date, categories, and tags. In a typical setup, a CSS selector is easier because it resembles how you select a block in the browser inspector. XPath is useful when you need to reach an element through a more complex structure. Save regex for edge cases where there is no proper DOM block or where you need to process an unusual text response.
| Method | When to use it | Risk | Verification |
|---|---|---|---|
| CSS selector | The page has clear classes or IDs for the title, article, or image. | The class may change after the source site is redesigned. | Open several items and make sure the selector pulls the same meaningful block each time. |
| XPath | The HTML is nested and the needed block does not have a convenient class or ID. | The path may be fragile if the structure changes. | Test not just one page, but at least several different source items. |
| Regex | You need to pull data from a text response or an unusual fragment. | It is easy to capture too much or break the rule on an edge case. | Test with different examples and keep the rule in drafts. |
| Auto | A quick initial test when the structure is simple. | Automatic detection may choose the wrong block. | Compare the result against a manual selector and the logs. |
Post template and variables
The template is where the import becomes a readable WordPress post. The documentation lists variables for the title, content, URL, image, categories, tags, and custom HTML blocks. Do not make the template too complex on day one. It is enough to output the title, the main text, a clean source link, the image, and if necessary a brief editorial note.
<p>Source: <a href="/%%item_url%%" rel="nofollow">go to the original</a></p>
%%item_content%%
This example is not a required formula. It shows the principle: the template should stay transparent. If you add an affiliate keyword replacer, random sentence generator, translation, or text spinner, do it later and only after verifying the base import. The more automated transformations you enable at once, the harder it becomes to understand where an error occurred.
Selectors, Live Scraper, and Shortcode for Targeted Output
Bulk rules create posts, while the live scraper outputs a data fragment inside an existing page. For that, you use the [crawlomatic-scraper] shortcode or a template tag. The documentation describes parameters such as url, query_type, query, output, cache, timeout, on_error, strip_links, strip_images, glue, eq, lt, gt, basehref, and others. It is powerful, but it requires discipline.
If the shortcode is placed on a public page, every visitor can indirectly trigger a request to the external source. That is why cache matters not just as a speed booster, but as protection against unnecessary requests. For a static or rarely changing block, use a long cache period. For a frequently changing block, you should still avoid an excessive timeout, otherwise a slow source will drag down your page.
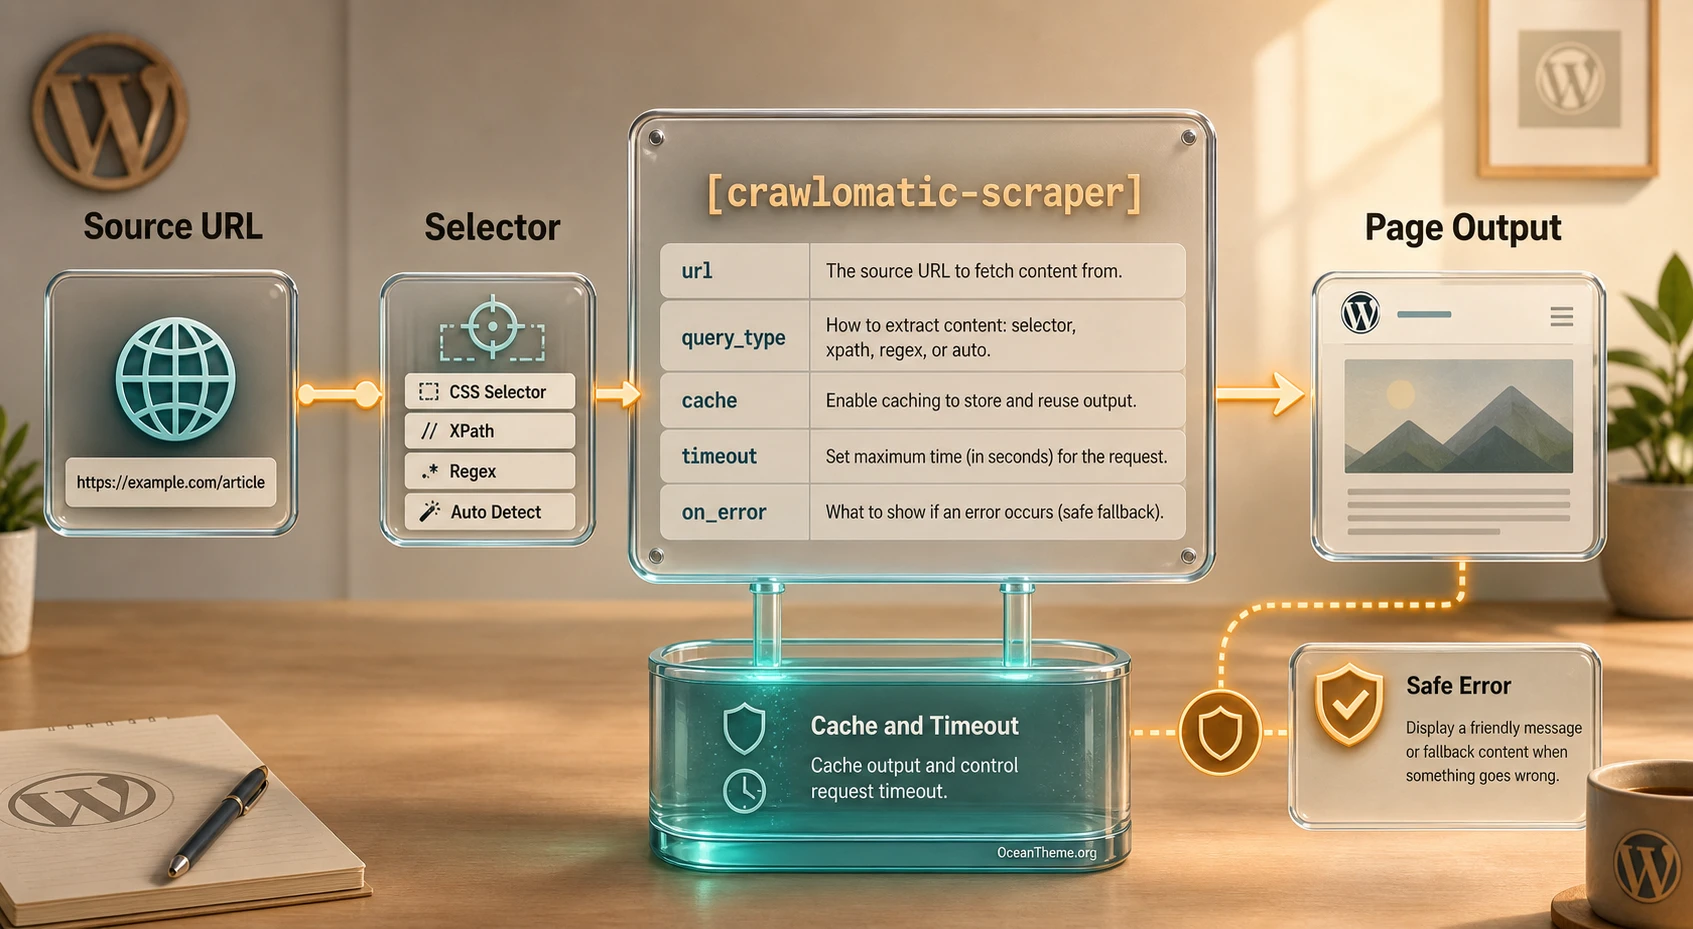
A safe shortcode logic example
Suppose you want to display one public metric from your own source. First, find the exact selector, then verify the result in a draft, then set output="text" if you do not need HTML. For errors, it is better to use a neutral message or hide the output so the public page does not expose technical details.
[crawlomatic-scraper url="https://example.com/status/" query_type="cssselector" query=".status-value" output="text" cache="1440" timeout="3" on_error="Data is temporarily unavailable"]In the real article HTML above, this is only a syntax example. Do not copy the URL and selector without adapting them. What matters more is understanding the mechanics: the URL should be stable, the selector should be precise, the cache should be long enough, and the error should be safe for the reader.
When not to use the shortcode
Do not place the live scraper in the site header, above-the-fold area, menu, checkout, lead form, or any critical block if the source is unstable. Do not use it for dozens of elements on one page without caching. Do not output raw HTML from a third-party site unless you have verified that it contains no extra links, embedded frames, junk markup, or unstable classes. For large imports, it is better to use a rule that creates drafts and reserve the shortcode for small fragments.
Practical Example: Importing a Section into Drafts and Verifying the Result
Let us walk through a scenario you can safely repeat on a test copy. The goal is to import several items from your own older section into WordPress, save them as drafts, pull in the title, main text, and image, remove unnecessary navigation links, assign a category, and verify that the result does not require a full manual cleanup from scratch.
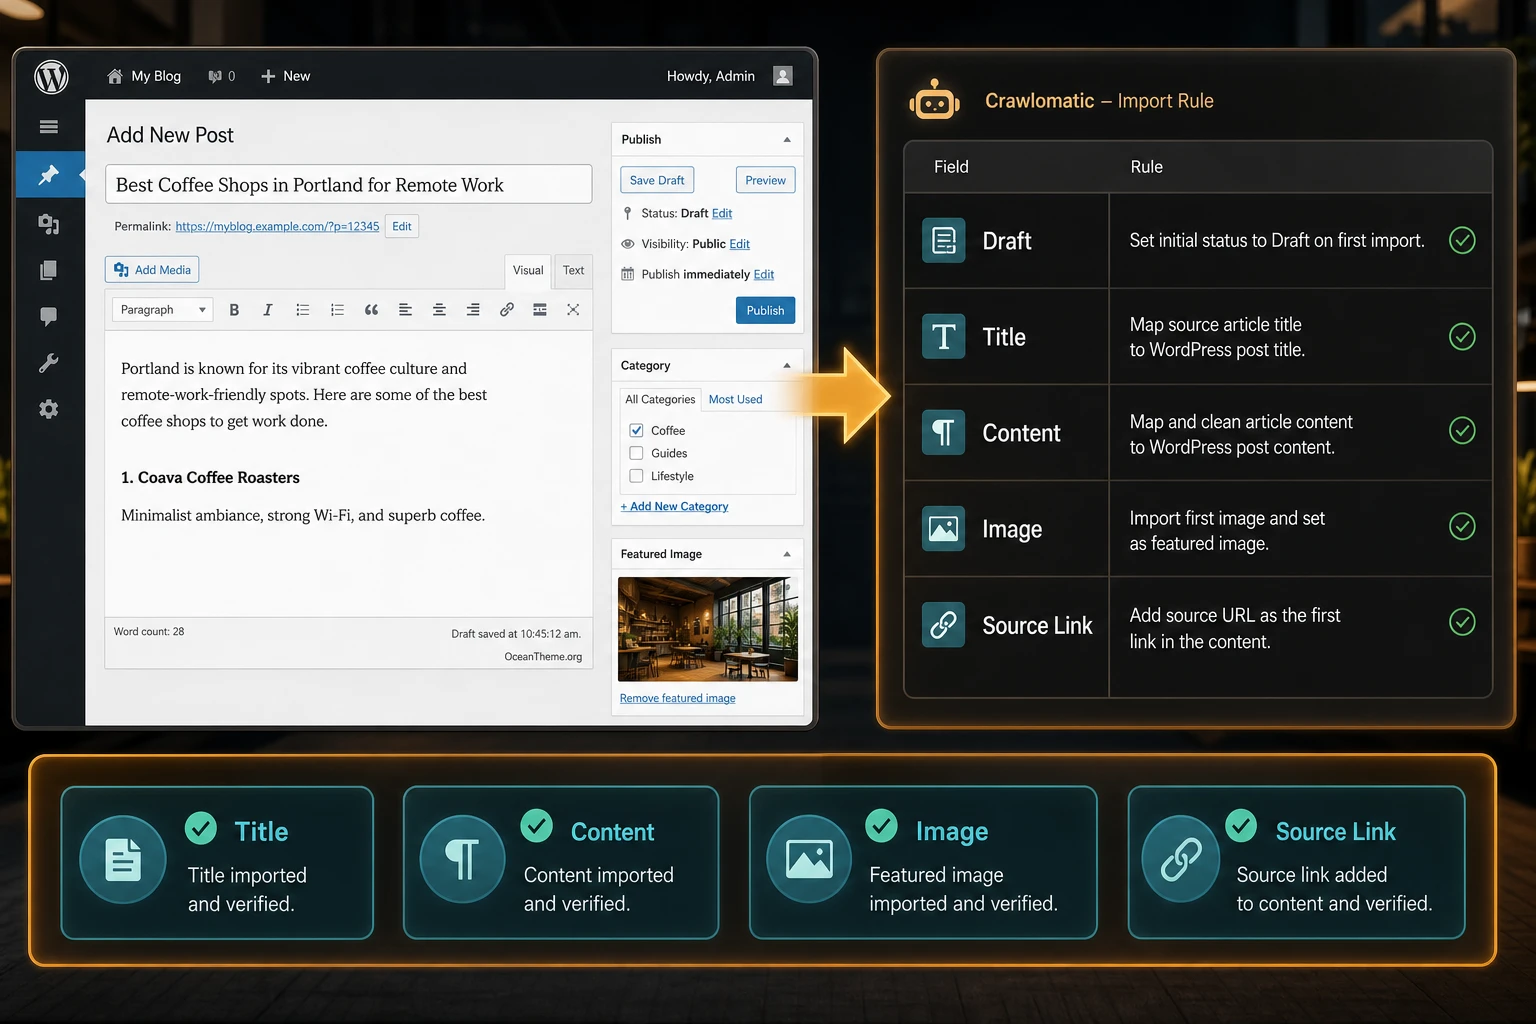
Goal
Get 3 to 5 drafts from an old section of the site where each post has a proper title, main text without menus or footers, a featured image, the category "Archive," a link to the original URL, and Draft status. No automatic publishing on the first run.
Preparation
- Create a category called "Archive - Review" or a similar technical category.
- Choose a starting page that lists links only to the items you need.
- Open one target source page and find the selector for the main text.
- Check a second and third item to make sure the selector is not unique to a single page.
- Prepare a post template with a source link and the main content variable.
Setup steps
- Create a new rule in
Web Crawl to Postsand paste in the starting URL. - Set
Max Posts At A Timeto a small value, such as 3 or 5, so the first batch stays manageable. - Choose
Post StatusasDraftand assign a technical author. - Restrict crawling of external links if the source does not require moving to another domain.
- For
Content Query Type, choose CSS selector or XPath, and forContent Query String, enter the article block you found. - Set separate selectors for the title and image only if automatic detection gets them wrong.
- Enable featured image import only if you have the rights to the images, and check where they are saved in the media library.
- Save the rule and click
Run Now.
Verifying the result
After the run, open the WordPress posts list and filter drafts by category or author. Check each post not only in the editor, but also in preview. The editor shows what was saved in the content, while preview reveals conflicts with the theme, shortcodes, lazy images, and CSS. If you see menus, breadcrumbs, or comment blocks inside the imported text, go back to the selector or add a strip rule by class or ID.
Quick takeaway: the first run is successful not when posts merely appear, but when each created post clearly matches the rule: correct source, correct content block, correct status, a proper image, and no unnecessary navigation.
The duplicate issue
If a repeat run does not create new posts, that is not always an error. In one support case, the developer explained that all available URLs had already been published, so the plugin did not continue importing in order to avoid duplicates. In that situation, check the list of already processed URLs, the rule logs, the crawl depth, and whether the source actually contains new material. If the source is truly exhausted, add new categories or a different starting URL instead of trying to force the rule to re-import the same pages.
Special Scenarios: News, Catalogs, WooCommerce, and Migration
Crawlomatic has a broad feature set, but different scenarios require different settings. One of the most common mistakes is trying to build one universal rule for everything. It is better to create separate rules for different sources and tasks. That makes it easier to control selectors, categories, templates, status, schedule, featured image behavior, and word-based limits.
News or reference section
For a news feed, the key settings are frequency, word filtering, content length, category mapping, and draft status. Do not import everything blindly. Enable required words if you only want material on a narrow topic, and banned words if the source mixes different sections. Add a source link to the template, and leave room for the editor to add an original intro or comment.
Catalog and WooCommerce
The Crawlomatic marketplace page mentions WooCommerce scenarios, including extracting prices and variations from certain sources. That does not mean every store will import perfectly. Products are more complex than regular articles: price, variations, stock status, attributes, gallery images, description, SKU, and tax settings all need to align with your store. Start with a test product, do not auto-publish it, check both the cart and the product page, and leave questionable fields for manual completion.
Migrating your own archive
For migrating an old site, Crawlomatic can be more convenient than manual copying if the HTML is repeatable. But output quality matters here. Start by importing a small section, then check internal links, images, titles, tables, code blocks, and old embeds. If the old site used unusual markup, it is better to add strip rules and a clean template now than to edit hundreds of posts later.
Frequently updated materials
Crawlomatic features include the ability to update created posts when the source page changes and move a post back to draft if the source URL becomes unavailable. These modes are useful for catalogs and reference sites, but enable them carefully. If an editor has already manually expanded an imported post, an automatic update could overwrite valuable changes. The safe approach is to start with a test category, then create a separate rule only for materials that truly need automatic updating.
How to Check Quality Without Hurting SEO
Publication automation should not turn your site into a warehouse of repeats. Even if the plugin imports content correctly, search value and user value still depend on your editorial work. For reference pages, add your own intro, context, comparison, practical validation, local examples, clarifications, and links to related materials. If the import is only for an internal archive, keep those posts out of indexing or out of public navigation until they are reviewed.
Checking a single post
Open the draft and walk through a short chain: title, first paragraph, main block, image, source link, category, excerpt, canonical, internal links, and mobile preview. If the text contains pieces of menus, ad buttons, cookie banners, social widgets, repeated author blocks, or comments, the selector is too broad. If the text is empty or too short, the source layout has changed or the query string no longer fits.
Checking a group of posts
After the first batch, review not only individual posts but also the category archive. Titles should not repeat, images should not all be the same placeholder, dates should not create a false timeline, and the excerpt should not consist of system text. If several posts look identical, stop the rule and improve the selector instead of manually deleting duplicates after every run.
Settings that help maintain quality
- Minimum Content Word Count helps prevent publishing empty or overly short imported pages.
- Maximum Content Word Count is useful when the source sometimes returns a full page with unnecessary blocks.
- Banned Words List helps filter out service content or unsuitable materials.
- Required Words List limits imports by topic when the source mixes multiple sections.
- Skip Posts That Do Not Have Images makes sense for catalogs and visually driven sections, but is unnecessary for regular text notes.
- Enable Logging for Rules helps you understand why a rule behaved the way it did.
Common Crawlomatic Problems and Troubleshooting
Problems with Crawlomatic usually do not come from a single cause. More often, they come from a combination: the source changed its HTML, the server runs out of time, the selector pulls the wrong block, the rule has already imported all URLs, the cache is showing an old result, and the logs are either too short or too verbose. Below is a practical troubleshooting flow without panic and without deleting the entire rule.
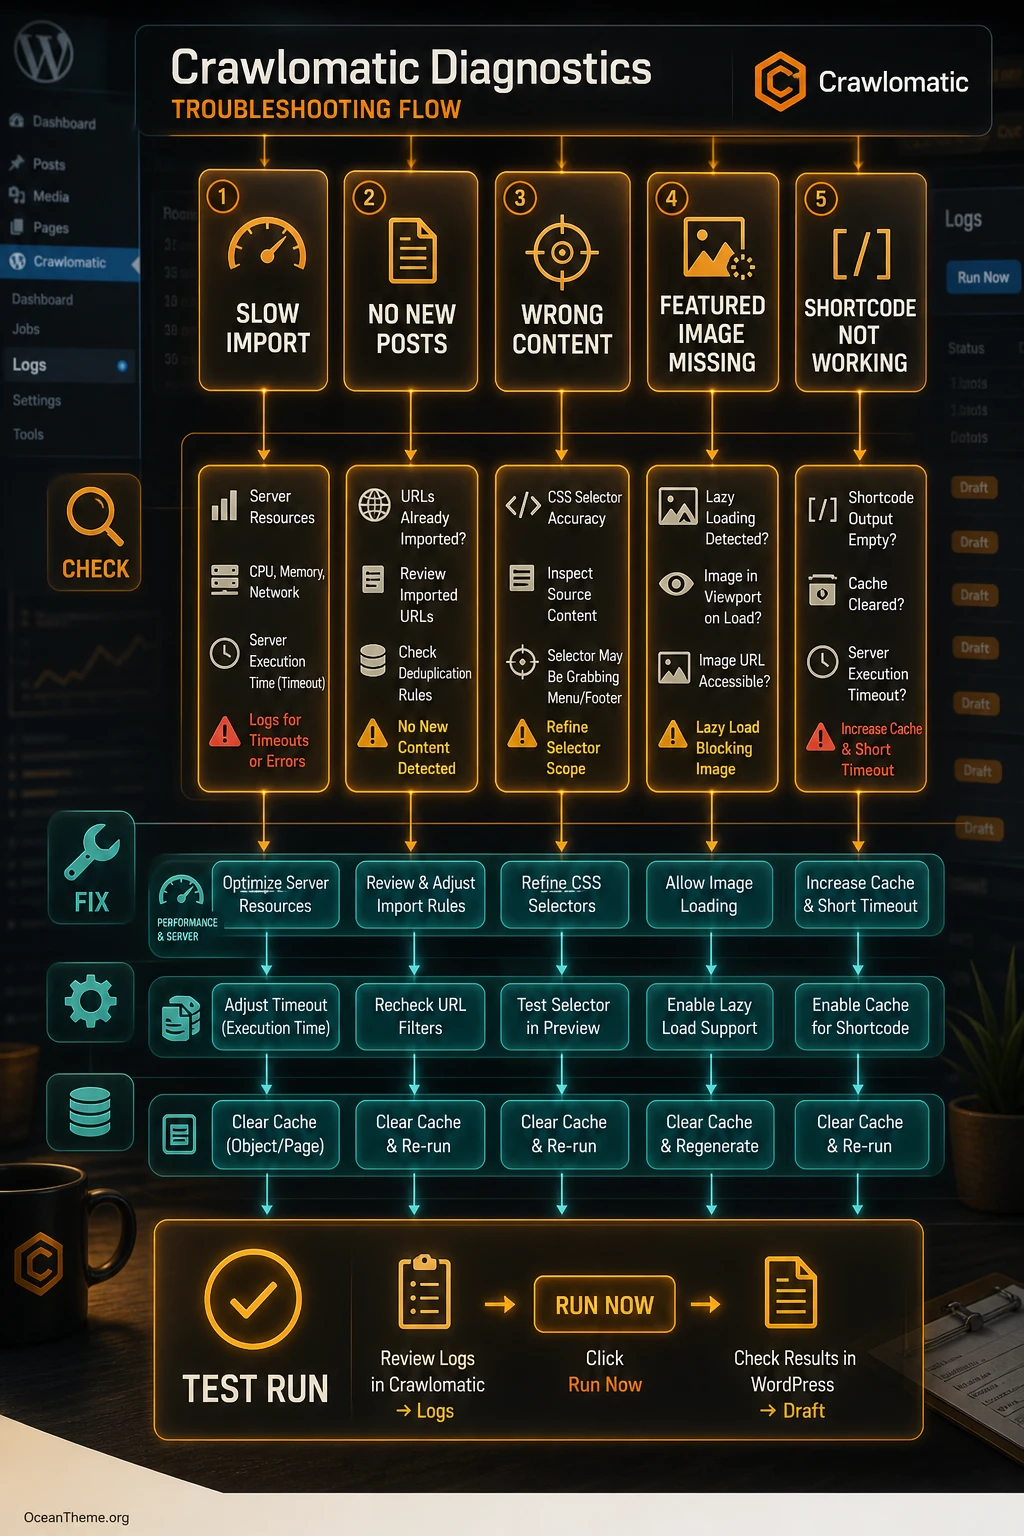
The rule runs, but no posts appear
Symptom: the rule shows a run or a yellow status, but no new posts are created. A likely cause is that all discovered URLs have already been imported, the starting page no longer contains new links, the crawl depth is too shallow, or filters are excluding everything. First, check the logs and the list of already created posts for the technical author. Then open the starting URL in a browser and confirm that it really contains new links.
Fix: add a new starting URL, expand the list of source categories, temporarily relax the filters, but do not blindly disable duplicate protection. If the rule stopped working after the source changed, check the link selector and the main content query.
The import is too slow
Symptom: a large batch takes many minutes to import, the rule hangs, or the server cuts off the process. The support developer noted that speed depends on CPU, memory, network, server limits, and the number of requests. Check Max Posts At A Time, timeout, crawl depth, images, headless modes, and the number of requests to the source. If you are importing hundreds of items, a small limit and multiple runs are safer than one massive process.
Fix: reduce the number of posts per run, disable unnecessary requests, skip image copying on the first test, configure cache for the live scraper, and review your hosting max execution time. If the source is slow, do not increase the timeout endlessly, because that can simply move the problem onto your own site.
The post includes the menu, footer, or an ad block
Symptom: the content is imported, but the post contains navigation, related articles, buttons, comment blocks, or the footer. The cause is almost always an overly broad selector or automatic detection. Inspect the target source page and find a narrower article container. If the correct block contains extra nested elements, use strip rules by ID or class.
Fix: replace auto query with a CSS selector or XPath, add remove or strip rules, and re-import 1 or 2 drafts. Do not try to clean every post by hand while the rule keeps generating the same junk.
The featured image is not saved, or the wrong image is used
Symptom: drafts have no image, or the plugin grabs a logo, a social media icon, or the first ad image instead of the real one. Check the automatic featured image setting, the image query, lazy load attributes, and whether you are allowed to copy the image locally. Sometimes the site stores the real image URL not in src, but in a lazy load attribute. The official video covers this as a separate topic.
Fix: provide a more precise featured image selector, configure the lazy load tag, temporarily disable image copying for troubleshooting, then check the media library and preview. If image rights are unclear, do not save them automatically.
The live scraper slows down the page
Symptom: the page with the shortcode loads slowly or occasionally shows an error. The cause is that the external source responds slowly, the cache is too short or disabled, the timeout is too long, or multiple shortcodes are placed on the page. Check how many live requests are made per page and how often the data changes.
Fix: increase cache, reduce timeout, set a neutral on_error, and leave only the truly necessary live fragments on the page. If the block is critical for conversions, it is better to store the data in WordPress as drafts or custom fields instead of fetching it on every view.
Rule behavior changed after an update
Symptom: after updating the plugin or the source, the rule starts pulling different content. Check the changelog, logs, selectors, and callback or shortcode settings. Because of security fixes, some risky callback processing methods may change. That is a normal cost of safer updates, but it should be accounted for on a test copy.
Fix: test the rule on staging, roll back questionable callbacks, replace complex processing with a safer selector or editorial review, and update the post template. If the rule depends on a non-standard PHP callback, do not move it to production without code review.
Safe Improvements and Working Habits
With Crawlomatic, careful operation is more valuable than code hacks. Official sources confirm many settings, but they do not provide a universal safe snippet for every site. So the items below are not core edits and not plugin file modifications, but a set of habits that reduce risk.
Separate rules by source
Do not build one rule for ten sites. Every source has its own structure, update frequency, selectors, images, and legal context. Separate rules are easier to disable, compare, and fix. If one source breaks, the others can keep working.
Keep imports in drafts until the rule is stable
Even if the first 3 posts look fine, the source may still have exceptions. Check different page types: a short note, a long article, a page without an image, a page with video, and a page with a gallery. Only after several clean runs should you consider Pending or automatic publication.
Restrict roles and shortcode usage
If the site has multiple authors, do not allow everyone to use scraping shortcodes without understanding the consequences. Crawlomatic security advisory history shows that shortcode callbacks and user permissions are not minor details. Ideally, plugin settings and scraped-content publishing should remain in the hands of an administrator or a trusted editor.
Watch the logs, but clean them up
Logs help you understand why a rule skipped a piece of content, where the source did not respond, which URL was already processed, and what happened during execution. But verbose logs can grow quickly and may sometimes contain sensitive request details. Turn on detailed logging for troubleshooting, then go back to the normal level and configure cleanup for older logs.
Video for Advanced Setup
The official CodeRevolution video tutorial for Crawlomatic is a useful visual companion to this article. It demonstrates lazy loaded images, content selection, the transition from single to serial scraping, basic and advanced settings in Web Crawl to Posts, pagination, Custom Shortcode Creator, Activity and Logging, Main Settings, proxy, image options, WooCommerce price modifications, and the live scraping shortcode. If you are configuring a complex rule for the first time, it is best to watch the video next to a test copy of your site, not on production.
The most practically useful parts are these: the opening shows a single import, then it moves into lazy images and choosing the correct content block, the middle of the video covers advanced settings, pagination, and extraction fields, and the final part covers logging, proxy, image options, WooCommerce price modifications, and shortcode. That addresses the intent of "how to use CodeCanyon Crawlomatic" far better than a short overview without screen examples.
FAQ on Configuring and Using Crawlomatic
Can I publish imported posts right away?
Technically, you can choose a published status, but that is a poor practice for a first rule. Start with Draft or Pending, review several batches, fix the selectors, and only then decide whether the rule can be trusted with automatic publishing.
Which should I choose: CSS selector, XPath, or regex?
For most HTML pages, start with a CSS selector. Choose XPath if the structure is complex and classes are not enough. Use regex only when DOM-based methods do not fit or the source returns a text format. If a regex can be replaced with a selector, it usually should be.
Why does Crawlomatic stop creating new posts after a repeat run?
A common reason is that the discovered URLs have already been imported, and the plugin avoids creating duplicates. Check the logs, the posts list, the starting URL, and whether new links exist on the source. If the source is exhausted, add another section or a sitemap rule instead of disabling duplicate protection.
Can I use the plugin with WooCommerce?
Crawlomatic features and changelog include WooCommerce scenarios, including prices, variations, and images. But products require stricter validation than articles. Test on staging, keep the status as draft, and review the product page, variations, price, image, and cart behavior.
Do I need to enable headless modes?
Only if the source truly loads the required content through JavaScript and a normal request cannot see the data. Headless modes make server load and troubleshooting more complex. If the source delivers normal HTML, start without them.
How do I avoid overloading my site with the live shortcode?
Use cache, a short timeout, a neutral on_error, and as few shortcodes on the page as possible. If the data matters on every page load, it is better to save it ahead of time through a rule or a custom field instead of requesting it from an external source on every view.
What security checks should I do before installation?
Check the current release, changelog, and security advisories, restrict user roles, do not let untrusted authors insert complex scraping shortcodes, keep a backup, and test updates on a copy of the site. For older versions, timely security updates are especially important.
When is Crawlomatic not a good fit?
If the source forbids reuse, the HTML changes constantly, the data is available only after complex authentication, an official API workflow is required, or there is no added editorial value, it is better to choose a different approach. Sometimes an RSS or XML importer, an API integration, or manual editorial preparation will deliver a more stable result.
When CodeCanyon Crawlomatic Is the Right Choice
CodeCanyon Crawlomatic is worth using when you have a clear source, a repeatable page structure, a legitimate reason to import the data, a test copy of the site, and a willingness to review the first batches manually. The plugin's strength is flexibility: seed URL, crawl depth, selectors, templates, statuses, featured images, logging, the live scraper shortcode, and special scenarios for catalogs or WooCommerce. The weakness of that same flexibility is the risk of misconfiguration and ending up with junk instead of a usable knowledge base.
The best strategy is simple: install the plugin on a test copy, build a small rule, keep posts in drafts, verify selectors across several pages, enable logging, evaluate the server load, and only then expand the schedule. If, along the way, you realize the source is better delivered through RSS, API, or JSON, do not stick with scraping just for the sake of scraping. Choose the method that gives you fewer errors and more control.
If that approach seems right for your site, you can move to the download section and get the CodeCanyon Crawlomatic file, then repeat the setup on a site copy first. That way, you will end up not just with an installed plugin, but with a controlled import process where every created post goes through a clear quality check.

