


AI Crawlers and Websites: How to Control Access to Your Content
Artificial intelligence is fundamentally changing how we search for information online by introducing new algorithms for automated data collection. Specialized AI crawlers continuously analyze millions of websites to train global language models and provide instant, accurate answers to end users. Understanding the hidden mechanisms behind these bots allows digital resource owners to effectively manage access to their content and reliably protect sensitive information. Properly configuring permissions and restrictions for crawlers is becoming a crucial element of modern technical SEO and cybersecurity strategies.
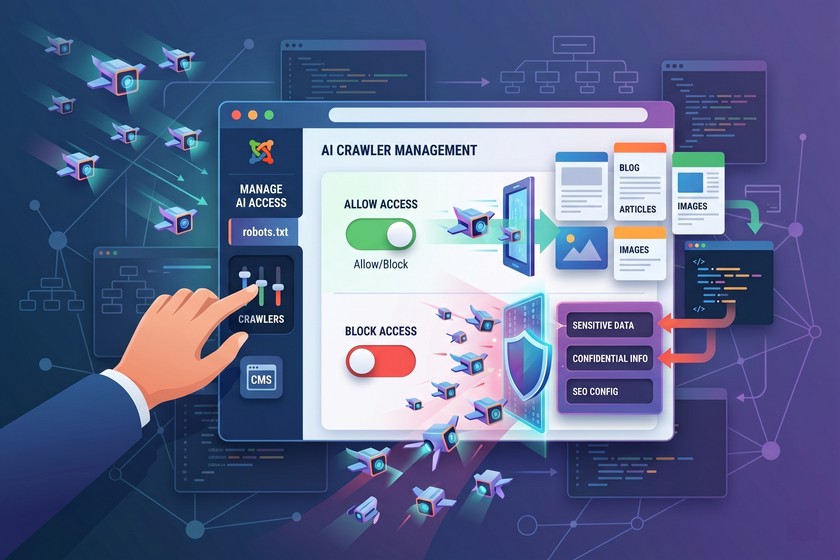
Websites are not created just to publish texts, and metadata is not configured just for fun - all these elements work together so that pages can be easily found by the target audience. For many years, traditional Google search has remained the primary source of organic traffic and the gateway to this visibility, largely thanks to its classic search engine bots (web crawlers).
Since the late 1990s, Googlebot and similar traditional crawlers have methodically crawled sites, downloaded HTML pages, and indexed them to help people find the information they need. As of early 2024, Google accounted for over 63% of all US web traffic distributed across the world's leading domains. This established clear rules of the game for SEO professionals.
However, the situation is changing rapidly now. According to recent large-scale market research, half of internet users now prefer turning to AI tools such as ChatGPT, Claude, Gemini, or Perplexity to get instant, structured answers without having to click through dozens of links. Moreover, even Google itself is actively integrating AI-generated summaries directly into search results through its AI Overviews features.
Behind these new intelligent interfaces is a rapidly growing class of bots known as AI crawlers. For administrators of projects running on the WordPress content management system, understanding how these new systems access and utilize published materials is more important today than ever before.
What are AI crawlers?
AI crawlers are specialized automated bot programs that scan publicly available web pages. In their architecture, they are similar to classic search engine bots, but they are built for a completely different purpose. Instead of indexing pages to rank them in traditional keyword-based search results, they gather massive volumes of text data to train large language models (LLMs) or to provide up-to-date, fresh information in response to live queries from AI chat users.
Broadly speaking, all existing AI crawlers can be divided into two main categories:
- Training crawlers: This group includes well-known bots such as GPTBot (from OpenAI) and ClaudeBot (from Anthropic). Their main task is the mass collection of historical and current data, which is then used by engineers to train neural networks so they can articulate thoughts more accurately, understand context, and answer complex questions.
- Live retrieval crawlers: A prime example is ChatGPT-User. These bots access websites on the fly, exactly at the moment a user asks a question that requires the freshest data (for example, checking the current price of a product, reading breaking news, or accessing up-to-date technical documentation).
There are other bots, such as PerplexityBot or AmazonBot, which build their own hybrid indexes or search engines to reduce their reliance on third-party information sources (like the Google Search or Bing indexes). And while the ultimate business goals of these corporations differ, their bots share one common trait: they actively request, download, and analyze content from millions of websites.
How AI crawlers work on a technical level
When an AI crawler visits a target server, the interaction process typically follows this predictable scenario:
- The bot sends a basic HTTP request (usually
GET) to the page's URL. In doing so, the bot performs no user actions - it does not interact with interface elements, does not scroll the page, and does not trigger DOM events. - The crawler receives and analyzes only the raw HTML code that the server returns in its initial response. In most cases, it does not wait for client-side JavaScript to load or execute.
- The system extracts all available
<a href="/...">links, image paths<img src="/...">, scripts<script src="/...">, and other resources, then adds internal (and sometimes external) URLs to its queue for further crawling. Often, these bots will even check broken links, generating 404 (Not Found) errors on the server. - The bot might attempt to load linked media files, CSS styles, or scripts, but purely as raw resources for parsing text or metadata, not for visually rendering and drawing the page design.
- This process repeats recursively, following all discovered links to map out the complete structure of the website.
An important technical note: Since most AI crawlers do not execute JavaScript code, any content that is loaded dynamically via AJAX or built using modern client-side React/Vue components often remains completely invisible to them. For comparison, the modern Googlebot has a fully-fledged rendering engine (based on Chromium) and indexes exactly what a live visitor ultimately sees in their browser window.
Nevertheless, these technological limitations are gradually disappearing as machine learning algorithms evolve extremely fast. Currently, most AI bots operate more like rapid, lightweight scrapers rather than full-fledged browser engines.
How AI crawlers interact with WordPress sites
The WordPress platform is a Server-Side Rendering system. It relies on the PHP programming language to dynamically generate complete HTML pages before they are ever sent to a user's browser or a bot. When a crawler visits a WordPress-powered resource, it instantly receives everything it needs in the response: the main text content, heading hierarchy, structured metadata, and navigation menus.
It is this server-side rendering architecture that makes the vast majority of WordPress sites highly crawler-friendly (SEO-friendly). Whether it's the classic Googlebot or the latest scraper from OpenAI, they can easily crawl the structure and seamlessly analyze the published material. In fact, this ease of crawling is one of the main reasons why WordPress-based projects traditionally perform exceptionally well both in classic search and on new AI-driven answer platforms.
Should you allow AI crawlers to access your content?
By default, AI crawlers can already read most WordPress sites without any hurdles. The main strategic question is not whether they can do it, but exactly which part of the information should be provided to them, and how to intelligently control this visibility.
Heated discussions are currently underway in the content marketing and digital business industries regarding this topic. This issue affects informational blog articles, corporate documentation, targeted landing pages - essentially, any text published in the public domain. Many experts advise "writing texts for machines," since neural networks increasingly retrieve data in real time and, most importantly, now include active links to original sources in their answers. A brand's presence in LLM responses is becoming just as desirable as ranking on the first page of Google.

Although the technology is still taking shape, AI crawlers are already having a direct impact on what information people receive when asking questions online. And this new audience acquisition channel could be critical for businesses.
A telling example comes from the CEO of the Vercel platform, who shared some statistics: referrals from ChatGPT chats accounted for nearly 10% of all new registrations on their service, whereas just six months ago, this figure did not exceed 1%. This clearly demonstrates how quickly AI referrals (links from neural networks) can turn into a powerful and independent customer acquisition channel.
The scale of AI crawler proliferation is also impressive. According to analytics from Cloudflare, AI bots visit roughly 39% of the internet's top million websites. However, only about 3% of the owners of these resources have taken real steps to block or restrict this specific traffic.
Thus, even if a site administrator hasn't made a final decision on access policies, AI crawlers are almost certainly already indexing the project on a regular basis.
Allow or block: a strategy for decision-making
There is no universal answer to this question, as every web project is unique. However, you can rely on the following basic framework for decision-making:
- Strict blocking: It is recommended to block crawlers from system-level, confidential, or low-value paths, such as
/login(login pages),/checkout(cart and checkout),/admin(control panel), or internal dashboards. Indexing these sections offers no benefit for brand visibility and only wastes server resources and bandwidth. - Open access: It makes sense to allow crawling for "informational content" - blog articles, detailed documentation, product descriptions, item specifications, and pricing pages. It is exactly these pages that have the highest chance of being cited in AI responses, which will drive high-quality, targeted traffic to the site.
- Tailored approach for paid content: Premium materials require a strategic decision. If the content itself is the core product (e.g., exclusive news, gated analytical research, paid online courses), then unrestricted access by AI bots to such texts could allow neural networks to summarize this material for users for free, directly undermining the business model.
The industry is also beginning to offer new monetization tools. For example, Pay Per Crawl models are being tested, which would allow site owners to charge AI companies micropayments for the right to access their databases. Although such initiatives are still in the closed testing phase, the idea is gaining strong support from major news publishers who want tight control over the use of their intellectual property.
On the other hand, many marketing professionals are urging caution. Blocking all AI bots by default could lead to a site's complete disappearance from neural network responses, which is critical for businesses relying on broad reach. Currently, the most pragmatic approach is a policy of selective openness: keeping open access to useful articles, strictly protecting utility sections, and regularly reviewing the rules as technologies evolve.
How to manage AI crawler access on WordPress sites
If the presence of neural network bots on a project raises concerns, or if fine-tuning their behavior is required, a WordPress administrator has a full suite of tools to regain control of the situation.
There are three main, proven methods for managing AI crawler access:
- Manually editing the
robots.txtsystem file. - Using specialized WordPress plugins to automate the process.
- Applying network-level protection (e.g., Cloudflare bot protection).
Below, each of these methods is broken down in full detail.
Option 1: Blocking AI crawlers manually via the robots.txt file
The robots.txt - file is a text document located in the server's root directory that tells bots which sections of the site they are allowed to crawl and which are strictly prohibited. Most well-behaved, legitimate AI crawlers owned by major corporations (GPTBot by OpenAI, Claude-Web by Anthropic, Google-Extended) strictly obey these rules (directives).
An administrator can completely block specific bots, grant them full access, or restrict the scraping of certain directories. For example, to completely deny access to key AI bots for the entire site (which is generally not recommended for public projects), you need to add the following code to your robots.txt file:
User-agent: GPTBot
Disallow: /

User-agent: Claude-Web
Disallow: /

User-agent: Google-Extended
Disallow: /
However, if the strategic goal is to allow full access for OpenAI's bot so the brand gets mentioned in ChatGPT responses, the directive would look like this:
User-agent: GPTBot
Disallow:
To block exclusively utility sections of the site, where the presence of crawlers brings no informational value (such as a user login page), a targeted restriction is applied:
User-agent: GPTBot
Disallow: /login/
Such selective blocking is the most professional approach. Sensitive paths (such as /wp-admin/, /cart/, or /checkout/) should always be hidden. At the same time, product catalogs, feature reviews, and help sections remain open for quote generation and referral traffic.
You can make changes to the robots.txt file in WordPress in several ways:
- Using popular SEO plugins (for instance, Yoast SEO or Rank Math, by navigating to the "Tools" -> "File Editor" section).
- Through file manager plugins installed right into the admin panel.
- By connecting directly to the server via FTP/SFTP and editing the file in any text editor.
Option 2: Using WordPress plugins
For users who prefer not to meddle with system files directly or are looking for a faster and safer way to manage crawlers, there are specialized plugins that let you configure protection in literally a few mouse clicks.
There are plugins available that include built-in support for blocking AI bots. In their interface, the administrator can use handy toggles to choose exactly which bots to deny access. Typically, the databases of such plugins are constantly updated, and most known AI bots (like the GPT and Claude scrapers) can be blocked by default.
Special attention should be paid to the Google-Extended bot. Its blocking is usually configured separately, and it is important to understand a key nuance: denying Google-Extended from crawling the site stops the use of its texts for training Google's neural networks, but it does not affect the site's rankings and its visibility in the classic Google Search results in any way.
Specialized solutions (for example, plugins in the "Block AI Crawlers" category) are built for one sole purpose - to give independent resource owners full control. They automatically add the correct Disallow directives to the virtual robots.txt for over dozens of known neural network bots without the need for manual configuration setups. These are lightweight open-source solutions that do not burden the server's database.
An important nuance: If a physical robots.txt text file is created on the server (instead of the virtual one generated by the WordPress core on the fly), most plugins won't be able to make changes to it due to file permissions. In this case, you will either need to delete the physical file, allowing the plugin to work with the virtual one, or transfer the settings manually.
Option 3: Using Cloudflare's bot blocker
If a WordPress project uses CDN and DNS services from Cloudflare (which is a modern standard for accelerating and securing sites), the administrator gains access to an ultra-powerful tool for blocking dozens of known and hidden AI bots at the data delivery network level.
Cloudflare recently launched a dedicated AI scraper and crawler protection feature that is available even on free tier plans. Unlike the robots.txt method (which relies on the honesty of the bot developers), Cloudflare analyzes network signals and blocks parasitic traffic before it even reaches the site's server. This protects against even those scrapers that disguise themselves as regular users or spoof their identifiers (User-Agent).
Activating basic protection takes just a few steps:
- You need to log into your Cloudflare dashboard.
- Go to the Security -> Settings section.
- In the filtering block, find the Bot traffic option.
- Turn on the Bot Fight Mode toggle.

Users on Cloudflare's paid plans gain access to the advanced Super Bot Fight Mode module. This is an enhanced version of the protection, offering flexible analytics capabilities and fine-grained rule tuning. It is based on complex heuristics and the deployment of JavaScript challenges into the visitor's browser. This makes it possible to detect so-called "headless browsers," hidden scripts for automated site scraping, and other resource-intensive malicious traffic.
For example, instead of a blanket ban on all automated requests, you can configure the firewall to strictly block only "definitely malicious automated traffic," while seamlessly letting through "verified bots" such as Google or Bing search engine crawlers, or useful site uptime monitoring services.

What this technological shift means for WordPress sites
AI crawlers have already firmly rooted themselves in the internet ecosystem and have become an integral part of how people search for information. This technology is still in the active formation stage: legal rules and technical standards continue to be refined, and site owners worldwide are testing various strategies, determining what volume of their knowledge they are willing to provide to neural networks for free.
The undeniable upside is that projects on the WordPress platform inherently start in a highly advantageous position. Thanks to a robust architecture that generates clean, semantically correct HTML code, most AI crawlers can quickly and flawlessly analyze content without the need to create special XML sitemaps or apply additional workarounds by programmers.
The main strategic decision for businesses today lies not in the technical capabilities to close off the site from bots, but in finding the perfect balance: how to provide neural networks with exactly the level of access that will foster brand awareness growth, without exposing unique commercial materials to the risk of theft. A combination of well-thought-out rules in robots.txt and powerful cloud protection against unwanted traffic allows you to build a solid foundation for the successful development of your resource in the new era of artificial intelligence.
Nearby Materials | ||||

|
Accessibility Testing for Extensions: How to Check WCAG Compliance | How to Use PHPStan to Test Joomla Extensions |

|
|

